AgentLab
A reproducible laboratory for studying the scaling behavior of LLM agent organizations.
AgentLab is a reproducible laboratory for empirical research on multi-agent LLM systems. Rather than providing new agent architectures, it provides the infrastructure to ask and answer controlled research questions: reproducible experiments, calibration gates, deterministic replay, and auditable analyses. Version 1.0 demonstrates this methodology through three empirical studies on Claude Haiku 5.5.
01Why I built this
Benchmarks for agent systems typically assume task difficulty rather than measuring it, and hidden evaluation artifacts can masquerade as findings. My first pilot made the point directly: every configuration scored a perfect fraction correct, because each agent carried a check tool inside its attempt and self-verified until the check passed — the experiment was measuring its own setup instead of the phenomenon. I wanted scaling claims about agent teams that I could trust, so I built the measurement infrastructure first, treating benchmark design, calibration, replay, and analysis as first-class research objects.
02Three methodological contributions
-
1. Artifact-resistant evaluation
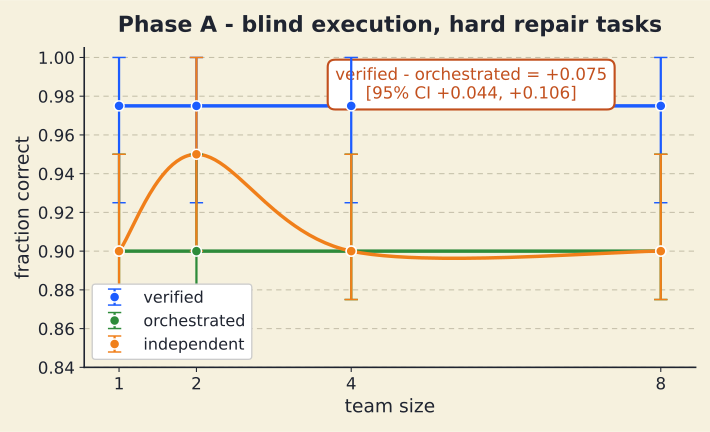
An experiment can measure its own setup instead of the phenomenon it claims to study, and the failure mode is silent: the numbers look clean. AgentLab pairs artifact audits — lenient-vs-strict rescoring, a no-work baseline, seed sensitivity — with blind execution protocols that remove internal self-verification, so this class of error is looked for, not stumbled into. Under blind execution, external verification produced a real improvement over matched orchestration, flat across team size: verification acts as per-subtask insurance, not as a scaling effect.
-
2. Calibration gates and mechanistic benchmarking
A scaling variable should change the mechanism, not just the amount of work. Hypotheses are pre-registered with their falsification criteria, and an offline calibration gate must first show that a benchmark measures what it claims — in Phase A-2, the gate rejected the first chain generator before any live run, because its operations made defects less visible at later positions. The corrected experiment still could not enter the error regime it was designed to study, and that was the reported conclusion. The platform rejected its own hypothesis for the correct reason.
-
3. Model-calibrated benchmark generation
Difficulty becomes a measured, controlled variable instead of an intuition asserted by the benchmark's author. A closed-loop controller calibrates a task family to a requested first-attempt failure band for the target model, and one requested band converged and validated on held-out seeds. For the 10% band, the calibration procedure correctly diagnosed that the current generator family cannot represent that operating point — the ladder jumps across that band in a single rung — so the controller declared failure against its pre-registered criterion rather than widening the tolerance or interpolating an answer.
03Get AgentLab
AgentLab v1.0 Release Repository
Every experiment ships as an immutable, sealed bundle with first-class provenance, deterministic replay, and analysis that consumes only recorded metrics — so another researcher can regenerate, replay, and audit each result.